Hire LLM engineers who have shipped to production traffic
Hire LLM engineers in India who have put GPT, Claude and open-weight models into production. Each salaried engineer clears a systems design interview, a live build and a cost exercise before you see their profile.
Clutch 4.8/5 from 33 verified reviews
50+ AI systems in production · ISO 9001:2015
to matched profiles
Senior LLM application engineer for RAG, tool calling, structured outputs and evals.
Trusted by teams at
What an LLM engineer does on your team
Most of the work sits around the model, in the retrieval, evals and monitoring that keep answers correct and inference affordable.
- What does an LLM engineer do?
- An LLM engineer builds software on top of large language models such as GPT, Claude, Gemini or Llama. The work covers prompt and tool design, retrieval over your data, structured outputs, evaluation, cost control and monitoring, so an LLM feature behaves the same way in production as it did in the demo.
LLM engineers available to hire
Hire one specialist for a single feature, or pair roles into a small pod.
LLM application engineer
Owns one LLM feature across the UI, backend, prompt layer and integrations, from first commit to release.
See LLM developmentLLM integration engineer
Wires model calls into CRMs, ERPs, ticketing tools and internal APIs through function calling, webhooks and MCP servers.
Prompt and LLM systems designer
Designs the prompt architecture, structured outputs and prompt versioning, plus the evaluation that shows whether a change made things better.
Agentic systems engineer
Builds multi-step agents with tool use and guardrails on LangGraph, CrewAI, AutoGen or the OpenAI Agents SDK.
Hire AI agent engineersFine-tuning engineer
Runs SFT and preference tuning, curates the datasets and designs the evals, for cases where prompting has hit a ceiling.
LLM reliability engineer
Owns observability, fallbacks, model routing and cost control for high-volume or business-critical LLM workloads.
Four gaps a CV will not show you
Calling a model API is a common skill. Keeping an LLM feature correct and affordable under production load is rarer, and our vetting tests for these four gaps.
Tutorial-only experience
Notebook demos hide rate limits, timeouts and messy inputs. We place engineers whose production LLM work is checked through references and work samples.
No way to measure quality
Without an eval set, every prompt change is a guess. Candidates design an evaluation alongside the prompt in the live challenge.
Costs that grow with usage
Inference spend often becomes the problem before answer quality does. A dedicated exercise tests caching, model routing and batching on a production workload.
Locked to one provider
Engineers who know one API tend to design around that one vendor. Our engineers work across OpenAI, Anthropic, Google and open-weight models, and pick per task.
How we vet LLM engineers
Three LLM-specific vetting stages, then a reference check. You see the vetting notes during CV review, before you commit to anything.
Hire an LLM engineer this month
Tell us the model, the data and the deadline. You get vetted profiles within 48 hours.
Models and tools our engineers use
Our engineers pick the model for each task based on the data involved and the budget.
Cost to hire LLM engineers
Dedicated LLM engineers start from $1,799 a month, full-time. Match the contract to the work. A senior architect for ten hours a week is often worth more than a full-time generalist.
| Full-time | Fractional | Project-based | |
|---|---|---|---|
| Commitment | 3+ months, embedded with your team | 10 to 30 hours a week | Defined scope with milestones |
| Typical length | Ongoing roadmap work | As long as you need the expertise | Set by the agreed scope |
| Best for | Sustained build capacity on an LLM product | Design reviews, critical integrations, fine-tuning | An agent workflow, RAG system or cost audit |
| Who manages day to day | You, inside your process | You, with a senior specialist | ScalaCode, against agreed milestones |
Full-time means dedicated, 160 hours a month. Compare every option on the Engagement models page.
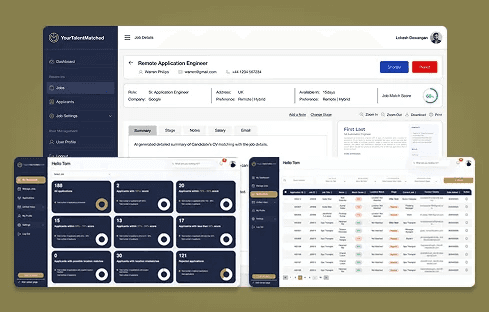
Talent Matched: a private LLM and voice screening
Talent Matched would not let candidate data go to a third-party model API, so our engineers set up a dedicated GPU server for its LLM. A recruiter writes a brief in plain English and the search covers 850 million external profiles plus the client's own database. Spoken screening answers get a score as well. Each employer on the platform has its own careers site.
Candidate ranking latency, per the client
More AI products our engineers built
All case studies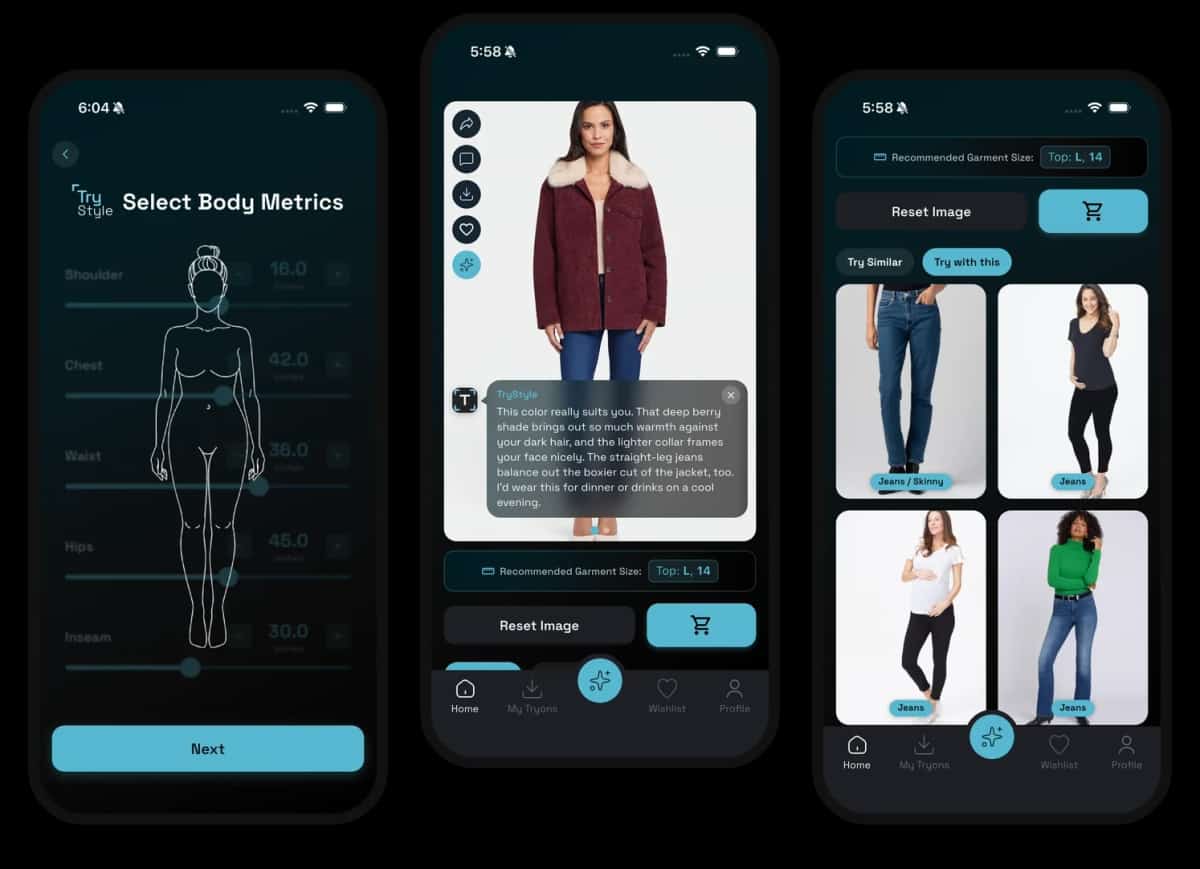
What clients say about our AI engineers
Verified reviews from Clutch and GoodFirms, and clients on camera.
33 verified reviews on Clutch
 Clutch review★★★★★
“What I found impressive about ScalaCode was their ability to listen to the soul of an educational mission.”
Clutch review★★★★★“What impressed me most was that they didn't just blindly build whatever we wrote down in the initial scope.”
Clutch review★★★★★“What stood out to us as most impressive and unique about ScalaCode was their ability to humanize complex AI.”
Clutch review★★★★★“What sets ScalaCode apart is their technical AI expertise and an understanding of a client's organizational ethos.”
 GoodFirms review★★★★★
“They built a high-performance, AI-powered platform that transformed video engagement for learning.”
Clutch review★★★★★“They managed to balance technical skill with an understanding of the marketing world.”
Clutch review★★★★★“Their team often proposed innovative features we hadn't considered.”
Hire LLM engineers FAQs
Dedicated LLM engineers start from $1,799 a month, full-time, the same as every other role.
How much does it cost to hire an LLM engineer?
Dedicated LLM engineers start from $1,799 a month, full-time and billed monthly, the same as every other role. Fractional and project work is quoted after the first call, and a production LLM application starts at $14,999.
Which models and frameworks do your LLM engineers use?
They work across GPT, Claude, Gemini, Llama and Mistral, and pick the model per task based on the data and the budget. Frameworks include LangChain, LlamaIndex, LangGraph, CrewAI, the OpenAI Agents SDK and MCP, with RAGAS, Promptfoo and Langfuse for evaluation.
How do you vet LLM engineers?
Each engineer clears a 90-minute systems design interview, a 3-hour live engineering challenge and a 60-minute cost and quality exercise. References and work samples confirm production LLM experience, and you see the vetting notes with every profile.
How fast can an LLM engineer start?
Vetted profiles reach you within 48 hours of the first call. After you interview and choose, onboarding takes about a week.
Can the engineer work inside our cloud and security policies?
Yes. Engineers work in your cloud accounts, repositories and identity setup under your access policies, on AWS, Azure OpenAI or GCP. Many projects use Azure OpenAI for compliance-sensitive paths and the direct API elsewhere.
Who owns the code, prompts and evaluation data?
You do. We sign a mutual NDA before sharing CVs, and the code, prompts, evaluation sets and other work product transfer to you under the engagement terms.
How is an LLM engineer different from a general AI developer?
An LLM engineer specialises in building on language models, including prompts, tool calling, structured outputs, retrieval, evals and cost control. A general AI developer may spend more time on classic ML such as training classifiers or forecasting models. For a chat assistant, an agent or document AI, hire the LLM specialist.
Can we hire an LLM engineer part-time?
Yes. Fractional engagements of 10 to 30 hours a week suit architecture reviews, critical integrations and fine-tuning work.
Which time zones do your engineers cover?
Our engineers work from India and overlap with US, UK and European business hours. For US clients the standard overlap is 4 to 6 hours of the US working day.
Your engineers work in your hours
Timezone overlap is built in. Your matched engineers keep 4 to 6 hours of daily overlap with US hours and a full working day with the UK, Europe and the Middle East, so standups, reviews and fixes land during your working day.
They built a high-performance, AI-powered platform that transformed video engagement for learning.
Tell us the use case and we will send LLM engineers who have built it before
- Profiles matched on model, stack and domain within 48 hours
- Vetting notes shared with every profile
- You interview and choose who joins
“They delivered on time and even offered ideas I hadn't considered.”
John-Paul Hatala, CEO, SnagPad